Skip to content
Ideas for a more human education
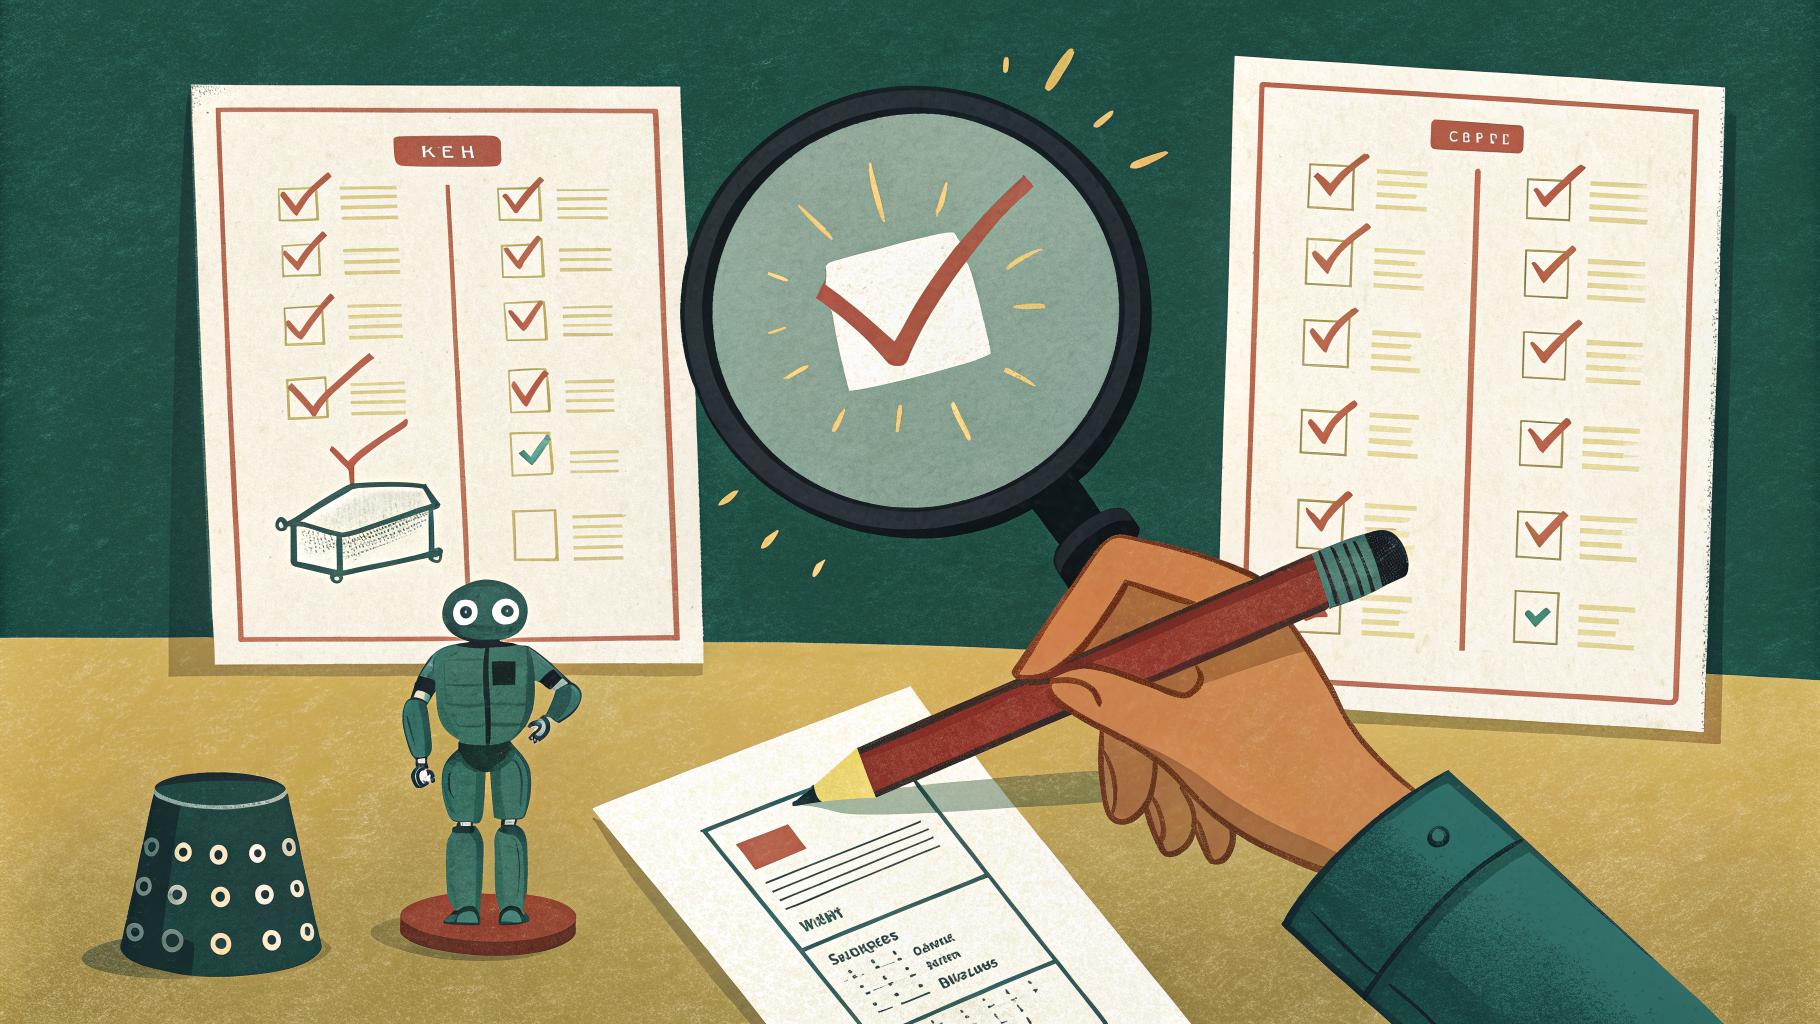
Magnifying glass over two answer sheets, one filled by a human hand, one by a robot hand, with a bell curve.
Illustration: Human Learning Review, made with AI. It does not depict real people or events.
Research · Policy & Ethics

Applying psychometric methods to distinguish between human and generative AI responses to multiple-choice assessments

Source: Computers and Education: Artificial Intelligence. Summarized by Human Learning Review.

Summary

This study asks whether person-fit statistics, a set of Item Response Theory tools that check how well an examinee's answer pattern matches what the model expects, can tell generative AI answers apart from human answers on multiple-choice tests. The authors compared chatbot responses with those of about 1000 human test-takers in each of 2 real assessments, a high-school chemistry test and a national university entrance exam.

  • Person-fit statistics found significant differences between human answer patterns and those produced by advanced chatbots, with ChatGPT, Claude and Gemini among those tested.
  • The chatbots showed up as aberrant respondents, meaning their answer patterns departed from what the model predicts for a typical examinee.
  • Different chatbots produced significantly different response patterns from one another.
  • Newer versions of generative AI performed better on the tests, and their answer patterns also moved closer to those of human examinees.

The authors argue that chatbots should be treated as a mixed group of separate intelligences, since their patterns differ, and that multiple-choice tests, which detection work has largely passed over as too hard to check, can be examined with existing psychometric methods. They conclude that Item Response Theory gives a sound framework for describing and separating human and AI response patterns on these tests, and they present the work as a theoretical and empirical base for that use. Their finding that newer models look more human-like in their answer patterns suggests the gap these statistics pick up may narrow as the tools improve.
Main findings

  • The authors found that person-fit statistics revealed significant differences between human and chatbot answer patterns on multiple-choice tests.
  • Chatbot responses appeared as aberrant, departing from the answer patterns the Item Response Theory model expects of a typical examinee.
  • Different chatbots produced significantly different response patterns, so the authors argue they should be treated as distinct intelligences.
  • Newer generative AI versions scored higher and also produced answer patterns that looked more like those of human test-takers.
  • The authors conclude that Item Response Theory offers a sound way to describe and separate human and AI responses on multiple-choice assessments.

This page is a short summary of a research paper. The full piece belongs to Computers and Education: Artificial Intelligence, and preprints may not have been peer reviewed.

Read the original at Computers and Education: Artificial Intelligence
A little room for reflection

A more considered
view of education.

Ideas worth sitting with. Practical questions worth asking. Human Learning Review, in your inbox.